Why industrial RFQs are difficult to automate
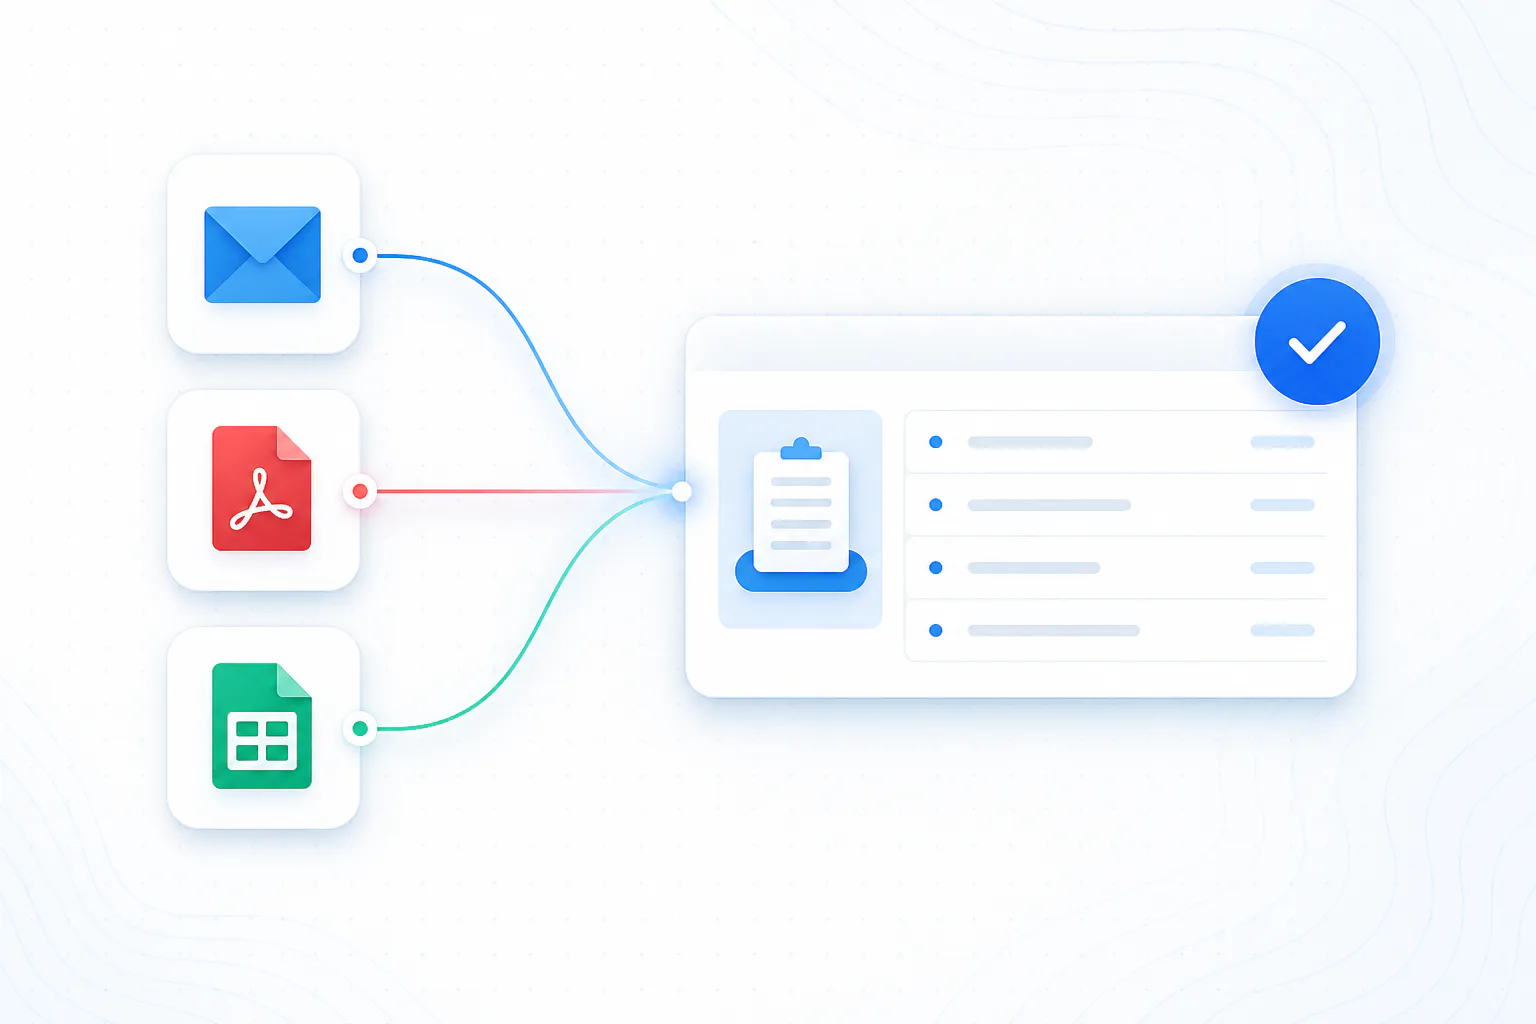
Industrial requests rarely arrive as clean rows in a system. A single opportunity may include an email, a tender PDF, an Excel line item schedule, supplier replies and internal pricing rules. Product descriptions vary, technical equivalents require judgment and commercial terms rarely line up. Automation must preserve this context instead of flattening it.
The useful goal is not a fully autonomous quote. It is a structured work package that gives an experienced reviewer faster access to requirements, evidence, supplier options, deviations and commercial assumptions.
What effective RFQ automation covers
A capable system should ingest mixed files, identify line items, normalize units and specifications, connect every extracted field to its source, compare supplier responses and calculate landed cost from approved rules. It should also expose uncertainty rather than silently guessing.
- Email, PDF and spreadsheet intake
- Source linked requirement extraction
- Supplier response matching
- Technical deviation detection
- Landed cost and margin controls
- Human approval before external action
Where AI belongs in the workflow
AI is strongest at interpreting unstructured material, retrieving related evidence and proposing matches. Deterministic rules are better for currency, freight, duty, discounts and margin. People should decide whether an equivalent is acceptable and whether a customer facing price can be committed.
This separation creates a safer operating model: AI proposes, approved rules calculate and accountable people approve.
How to evaluate RFQ automation software
Test software on historical RFQs that your team already understands. Measure extraction accuracy, evidence coverage, corrections per line, preparation time and the quality of surfaced exceptions. A useful pilot should run beside the existing process without sending emails or changing live ERP records.
Start with the hardest representative cases
A polished sample RFQ proves very little. Build an evaluation set that includes mixed file types, incomplete descriptions, revised attachments, supplier no-bids, technical alternatives and at least one case with difficult landed-cost assumptions. The set should reflect the work that consumes experienced time, not only the work that is easiest to demonstrate.
Keep the expected interpretation for each case beside the source documents. This gives reviewers a stable basis for identifying missing requirements, unsupported values and incorrect line-to-offer matches.
- Multi-line customer RFQs
- PDF and spreadsheet combinations
- Revisions and conflicting values
- Partial supplier responses
- Technical deviations
- Currency, freight and duty assumptions
Measure preparation quality as well as speed
Time to first draft matters, but it should not be the only measure. Track how much of the draft is supported by evidence, how many fields a reviewer changes, how many exceptions the system misses and how long it takes to reach a review-ready state. Separate system preparation time from supplier waiting time and internal approval time.
A faster draft that hides uncertainty can create more work later. The useful outcome is a draft that lets the reviewer reach a sound decision with less reconstruction and fewer unflagged errors.
Define the approval boundary before integration
Decide which actions are read-only, which outputs are suggestions and which actions require named approval. During an early evaluation, customer prices, technical-equivalence decisions, supplier emails and ERP writes should remain outside autonomous execution.
Integration should follow evidence that the core workflow is useful. Begin with exported or historical material, validate the work package, then add narrowly scoped access with logs, permissions and a clear rollback path.